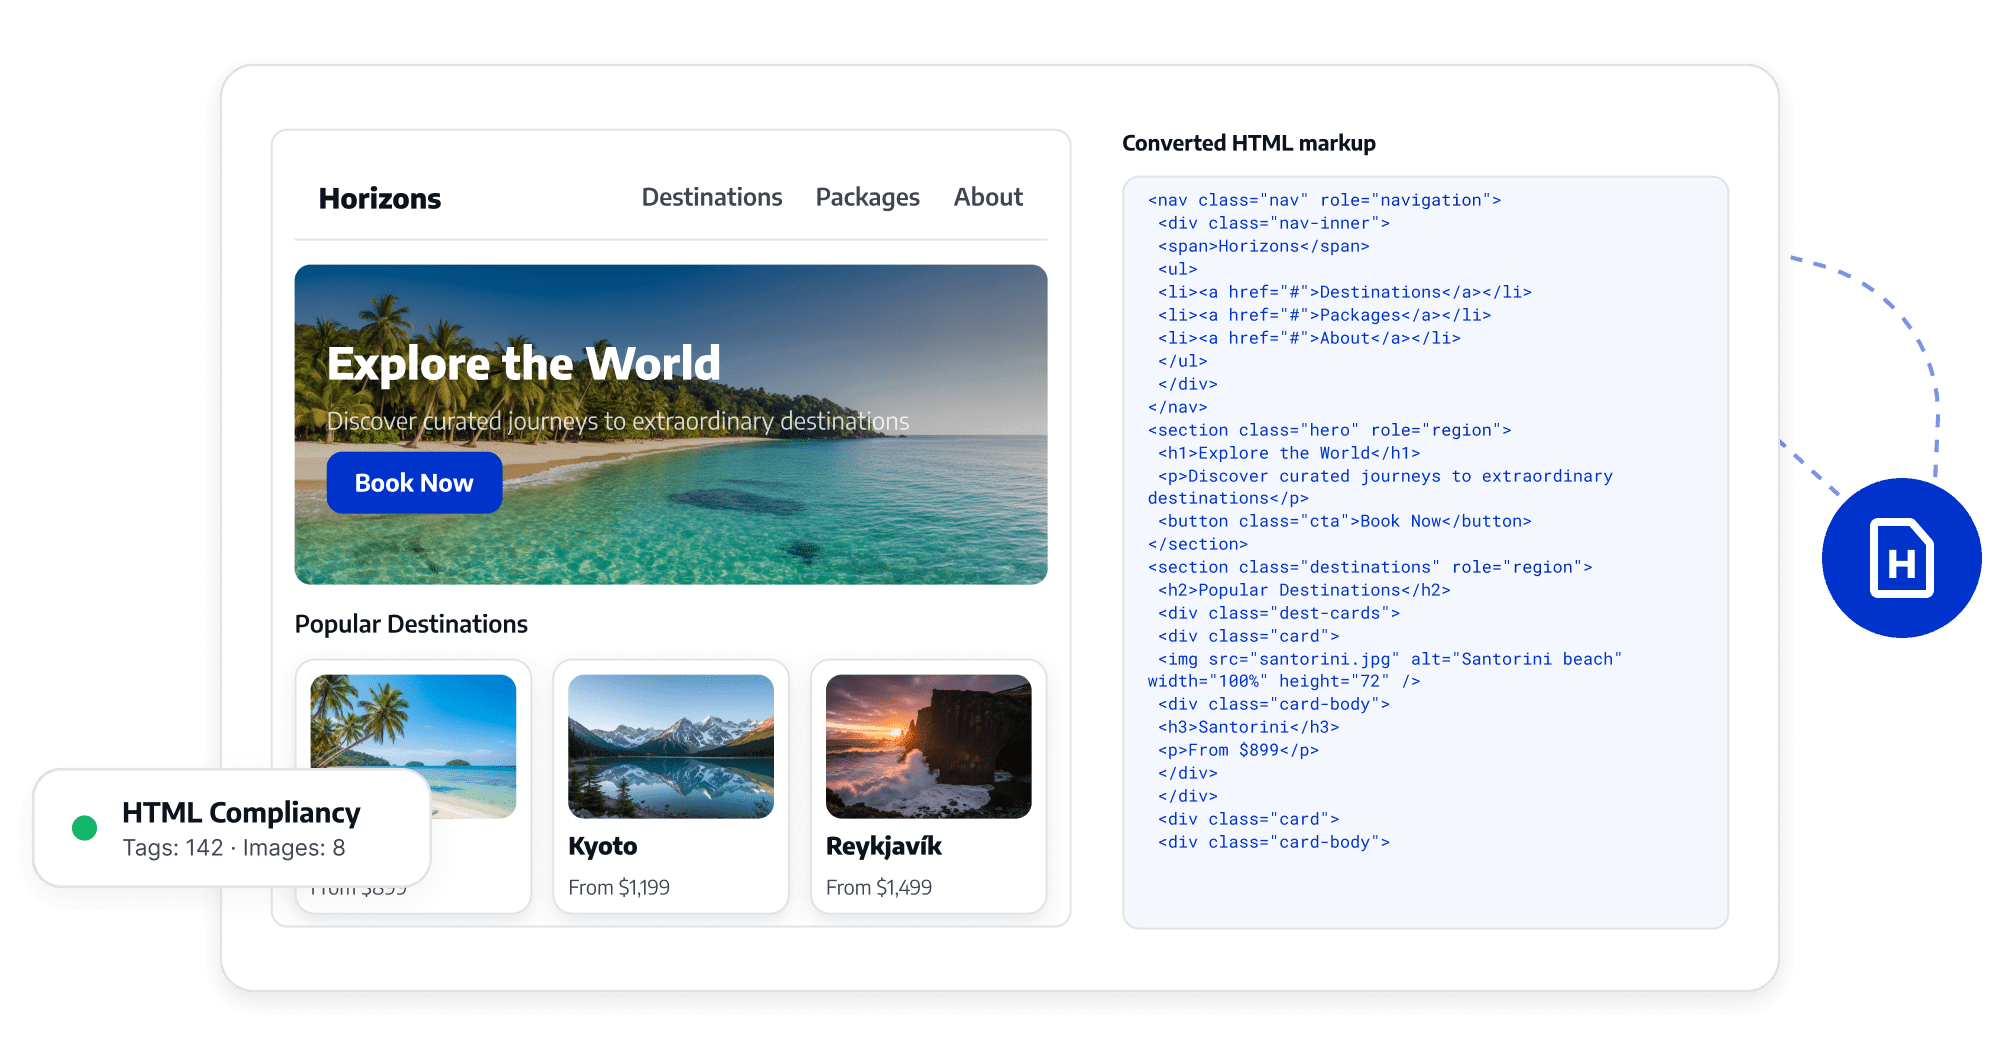
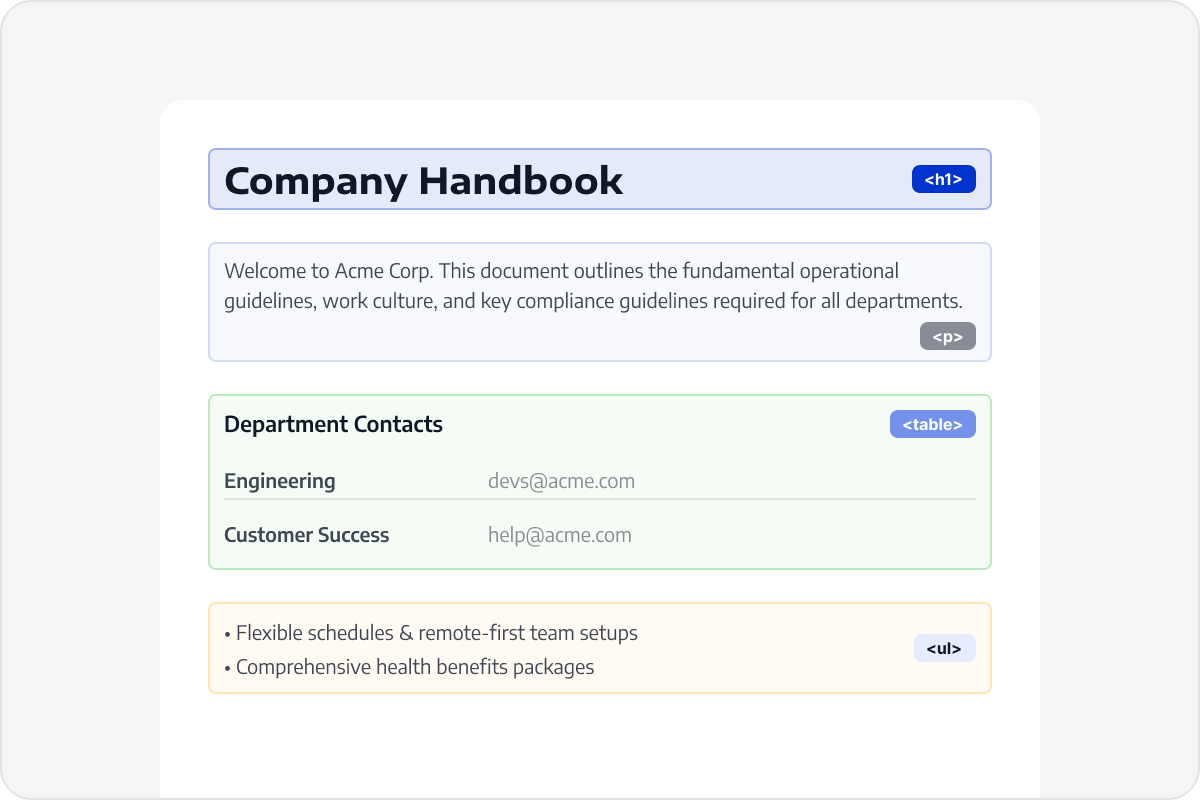
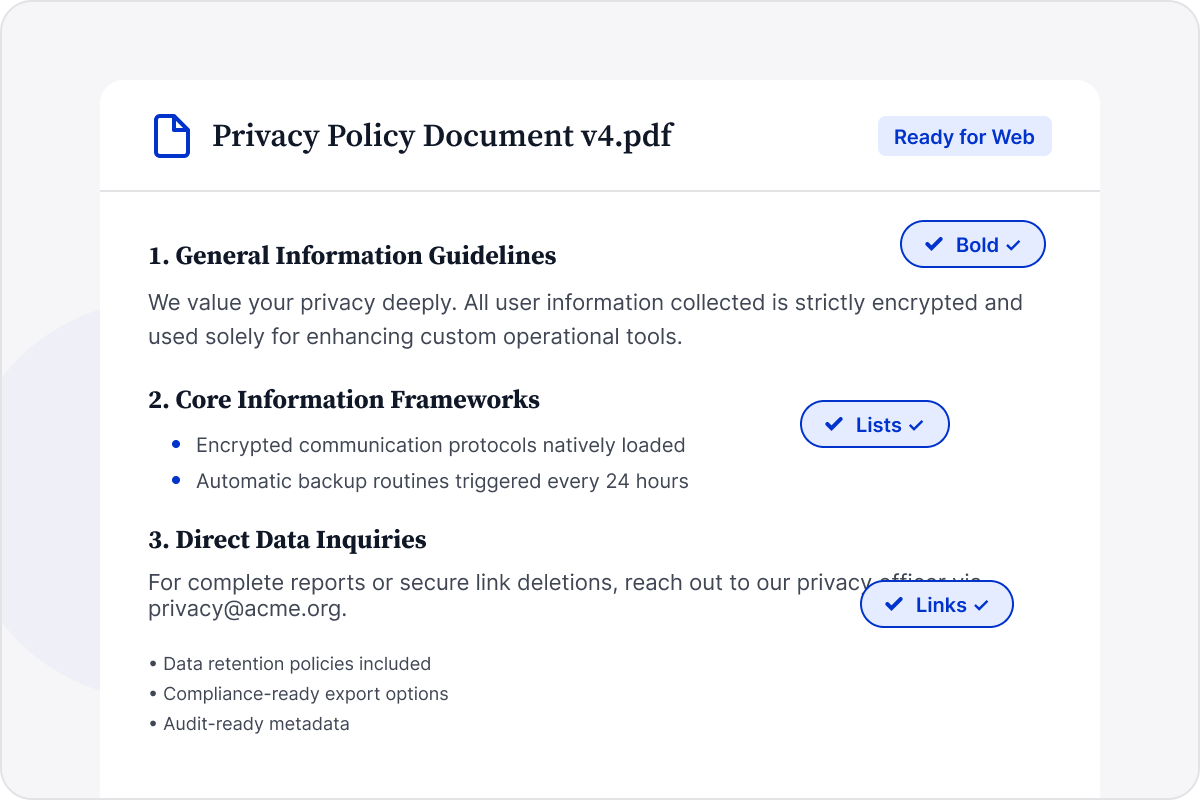
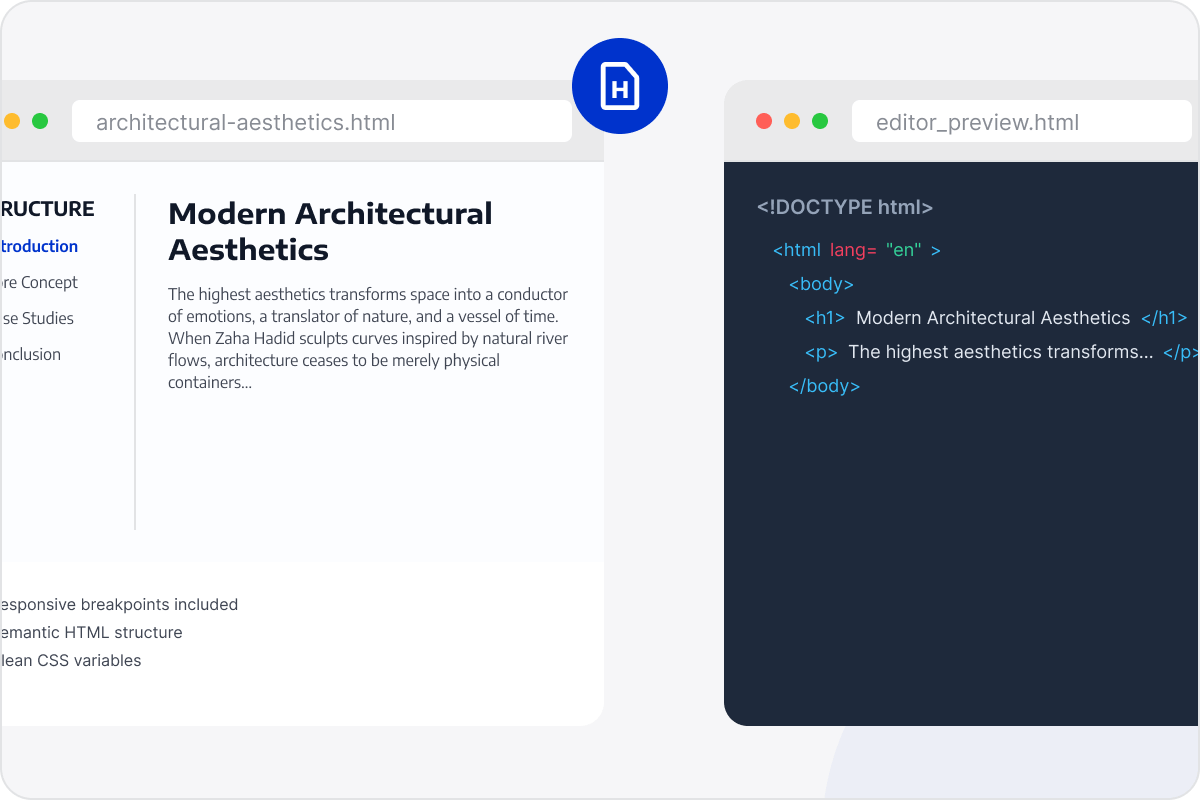
Identify text, images, fonts, colors, and basic layout information in the PDF to provide the content and visual basis for generating HTML.
Generate HTML Files
Generate HTML from the parsed content while preserving fonts, colors, spacing, and page relationships where possible, reducing the need to write CSS from scratch.
Reduce Reconstruction Errors
Reduce manual copying and style adjustments against the PDF, lowering the risk of differences in text, images, and page relationships during reconstruction.
Maintain Consistent Conversions
Use the same process across multiple PDFs to keep page structure and basic styling consistent and reduce layout differences between files.
Make Content Easier to Maintain
Review the converted content and layout, then update text, images, and styles in HTML without rebuilding from the PDF each time.
Access LynxPDF Expert Library
Forward-looking insights and strategic guides for enterprise document management.
Our specialists are available to address your enquiries regarding LynxPDF. Please complete the form below, and a representative will contact you shortly:
Commence your 14-day trial of LynxPDF and the LynxPDF Admin Console.
Identify the optimal pricing structure for your organisation.
Explore bespoke implementation scenarios and enterprise case studies.